Setting Up Data Observability Dashboards with Prometheus and Grafana
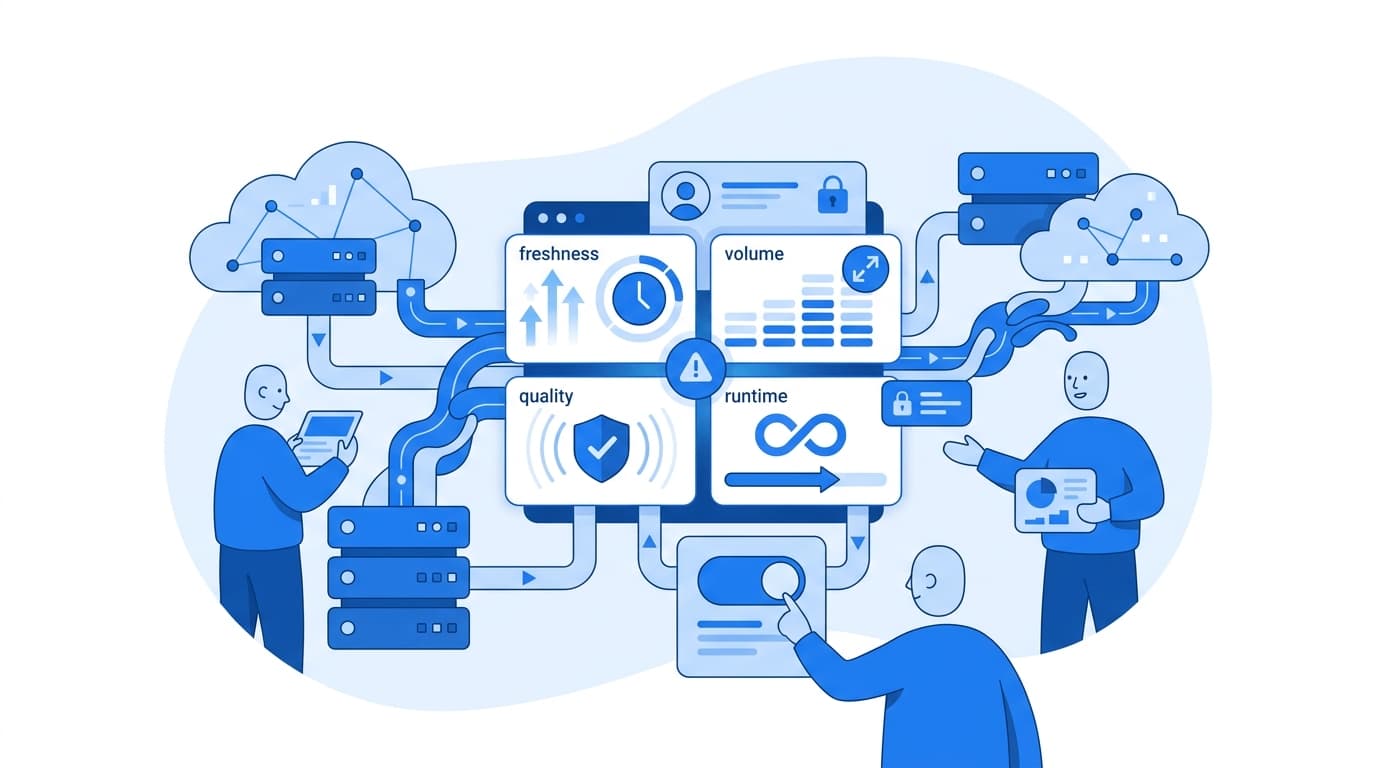
To set up data observability dashboards with Prometheus and Grafana, instrument each pipeline to emit a small set of health metrics (freshness, volume, quality, and runtime), get those metrics into Prometheus by scraping long-running services or pushing from batch jobs through the Pushgateway, encode your expectations as recording and alerting rules, and then provision Grafana dashboards as code that answer one question per panel: is this data trustworthy right now? The rest of this post walks through each step with working configuration, plus the design decisions we've learned to make early so the setup stays useful after the first month.
Why Data Observability Needs Its Own Metrics
Most teams already monitor infrastructure. CPU, memory, and pod restarts tell you whether a job ran. They don't tell you whether the job produced correct, complete, timely data. A pipeline can succeed with exit code 0 while loading half the expected rows, or while a source quietly started sending nulls in a key column.
Data pipeline monitoring closes that gap by treating the data itself as the thing under observation. In our experience, four signals cover most failure modes:
- Freshness: When did this dataset last update successfully?
- Volume: How many records did the last run process, and is that normal?
- Quality: What share of records failed validation, or had nulls in required fields?
- Runtime: How long did each stage take, and is it trending upward?
This mirrors the "four golden signals" idea from Google's SRE book (Monitoring Distributed Systems): pick a small number of signals that map directly to user-visible harm, and alert on those rather than on everything you can measure.
Step 1: Instrument Your Pipelines
Choose the right collection model
Prometheus pulls metrics by scraping HTTP endpoints. That works well for long-running services such as a streaming consumer or a model-serving API. Batch jobs are different: a nightly job may finish before Prometheus ever scrapes it.
The Prometheus documentation is explicit that the Pushgateway is intended for service-level batch jobs and not as a general-purpose push mechanism (When to use the Pushgateway). We follow that guidance:
- Streaming and serving workloads: expose
/metricsand let Prometheus scrape. - Scheduled batch jobs: push a final set of metrics to the Pushgateway at the end of each run.
Emit per-run metrics from batch jobs
For batch jobs, we use gauges that describe the last run rather than counters. Pushed counters reset each run and become confusing to query. Here is a minimal Python example using the official prometheus_client library:
import time
from prometheus_client import CollectorRegistry, Gauge, push_to_gateway

PIPELINE = "orders_daily"
registry = CollectorRegistry()

last_success = Gauge(
    "pipeline_last_success_timestamp_seconds",
    "Unix time of the last successful run",
    ["pipeline"], registry=registry,
)
rows_processed = Gauge(
    "pipeline_rows_last_run",
    "Rows written by the last run",
    ["pipeline", "stage"], registry=registry,
)
null_ratio = Gauge(
    "pipeline_null_ratio",
    "Share of rows with nulls in required columns",
    ["pipeline", "column"], registry=registry,
)
duration = Gauge(
    "pipeline_duration_seconds",
    "Wall-clock duration of the last run",
    ["pipeline"], registry=registry,
)

start = time.time()
df = run_pipeline()  # your extract/transform/load logic

rows_processed.labels(PIPELINE, "load").set(len(df))
for col in ["customer_id", "order_total"]:
    null_ratio.labels(PIPELINE, col).set(df[col].isna().mean())

duration.labels(PIPELINE).set(time.time() - start)
last_success.labels(PIPELINE).set_to_current_time()

push_to_gateway("pushgateway:9091", job=PIPELINE, registry=registry)
Two details matter here. First, last_success is only set after the job finishes cleanly, so a failed run leaves the old timestamp in place and freshness alerts fire naturally. Second, the metric names follow Prometheus naming conventions: base units (seconds), a _total suffix reserved for counters, and a clear prefix.
Keep label cardinality bounded
Every unique label combination creates a new time series. Labels like pipeline, stage, and column are bounded and safe. Labels like customer_id, file_name, or run_id are not, and they will degrade Prometheus over time. If you need per-record detail, that belongs in logs or your data quality tool, not in metrics.
Step 2: Configure Prometheus
Add scrape jobs for the Pushgateway and any long-running services. Note honor_labels: true on the Pushgateway job, which preserves the job and instance labels pushed by your batch jobs instead of overwriting them (Pushgateway README).
# prometheus.yml
global:
  scrape_interval: 30s
  evaluation_interval: 30s

rule_files:
  - /etc/prometheus/rules/data_observability.yml

scrape_configs:
  - job_name: pushgateway
    honor_labels: true
    static_configs:
      - targets: ["pushgateway:9091"]

  - job_name: model-serving
    static_configs:
      - targets: ["scoring-api:8000"]
Step 3: Encode Expectations as Rules
Dashboards are for investigation. Alerts are for interruption. We write both from the same rules file so the definition of "healthy" lives in one place and goes through code review.
# rules/data_observability.yml
groups:
  - name: data-observability
    rules:
      - record: pipeline:freshness_seconds
        expr: time() - pipeline_last_success_timestamp_seconds

      - alert: PipelineStale
        expr: pipeline:freshness_seconds{pipeline="orders_daily"} > 26 * 3600
        for: 10m
        labels:
          severity: page
        annotations:
          summary: "{{ $labels.pipeline }} has not succeeded in over 26h"

      - alert: PipelineVolumeDrop
        expr: |
          pipeline_rows_last_run{stage="load"}
            / (pipeline_rows_last_run{stage="load"} offset 7d) < 0.5
        for: 30m
        labels:
          severity: ticket
        annotations:
          summary: "{{ $labels.pipeline }} loaded under half of last week's volume"

      - alert: RequiredColumnNulls
        expr: pipeline_null_ratio > 0.01
        for: 15m
        labels:
          severity: ticket
A few practical notes:
- Freshness thresholds should reflect the schedule plus a buffer. A daily job gets 26 hours, not 24, so a slightly late run doesn't page anyone.
- Volume comparisons against
offset 7dhandle weekly seasonality better than comparing to yesterday. Tune the ratio per pipeline; the 0.5 above is a placeholder, not a recommendation. - Severity routing matters. Paging on every null spike burns out on-call engineers quickly. Reserve pages for staleness on datasets that downstream consumers depend on.
Step 4: Build Grafana Monitoring Dashboards as Code
Clicking dashboards together in the UI works for exploration, but it drifts. Grafana supports file-based provisioning for both data sources and dashboards, which lets you version them alongside the pipeline code.
# grafana/provisioning/datasources/prometheus.yml
apiVersion: 1
datasources:
  - name: Prometheus
    type: prometheus
    access: proxy
    url: http://prometheus:9090
    isDefault: true
# grafana/provisioning/dashboards/data.yml
apiVersion: 1
providers:
  - name: data-observability
    folder: Data Platform
    type: file
    options:
      path: /var/lib/grafana/dashboards/data
Recommended panel layout
We organize a pipeline overview dashboard top to bottom, from "should I worry?" to "why?":
- Freshness table (stat or table panel):
pipeline:freshness_seconds / 3600, with thresholds colored green, amber, and red per pipeline SLA. - Volume trend (time series):
pipeline_rows_last_run{pipeline="$pipeline"}overlaid with the same query usingoffset 7d. - Quality (bar gauge):
pipeline_null_ratio{pipeline="$pipeline"}broken out by column. - Runtime (time series):
pipeline_duration_seconds{pipeline="$pipeline"}to catch gradual slowdowns before they breach a schedule. - Active alerts (alert list panel): filtered to the current pipeline.
Define $pipeline as a template variable with the query label_values(pipeline_last_success_timestamp_seconds, pipeline). One dashboard then serves every pipeline, and new pipelines appear automatically once they start emitting metrics.
Extending the Setup to MLOps Monitoring
Model-serving services are long-running, so they can expose histograms directly. This makes MLOps monitoring a natural extension of the same stack rather than a separate system.
from prometheus_client import Histogram, start_http_server

prediction_score = Histogram(
    "model_prediction_score",
    "Distribution of model output scores",
    ["model", "version"],
    buckets=[0.1, 0.2, 0.3, 0.4, 0.5, 0.6, 0.7, 0.8, 0.9, 1.0],
)

start_http_server(8000)

def predict(features):
    score = model.predict_proba(features)[0][1]
    prediction_score.labels("churn", "v3").observe(score)
    return score
A simple drift signal compares the median score now against the same window last week:
histogram_quantile(0.5, sum by (le) (rate(model_prediction_score_bucket{model="churn"}[1h])))
-
histogram_quantile(0.5, sum by (le) (rate(model_prediction_score_bucket{model="churn"}[1h] offset 7d)))
This is a coarse indicator, not a statistical drift test. It tells you something changed and is worth investigating. For rigorous tests such as population stability or KS statistics, compute them in a scheduled job and push the result as a gauge, which keeps Prometheus doing what it does well.
Common Pitfalls We See
- Alerting on everything. Start with freshness on your most consumed datasets. Add volume and quality alerts as you learn each pipeline's normal behavior.
- Treating the Pushgateway as permanent storage. Metrics persist there until deleted. If you decommission a pipeline, delete its group, or it will report stale values forever.
- Unbounded labels. Covered above, but it's the most frequent cause of an unhealthy Prometheus instance.
- No owner per dashboard. A dashboard without an owning team rots. Put the owning team in the dashboard description and in alert labels.
If you're weighing how this fits into a broader platform strategy, our overview of data and MLOps engineering capabilities covers the surrounding practices, and our industry pages discuss how observability requirements shift in regulated environments.
FAQ
Is Prometheus suitable for data observability, or only for infrastructure?
Prometheus works well for data observability when you emit aggregate, low-cardinality metrics such as freshness timestamps, row counts, and null ratios. It is not designed to store per-record detail, so pair it with logs or a data quality framework for row-level investigation.
Should batch pipelines push metrics or be scraped?
Short-lived batch jobs should push their final metrics to the Pushgateway, as the Prometheus documentation recommends for service-level batch jobs. Long-running services, including streaming consumers and model APIs, should expose an endpoint and be scraped.
What are the most important metrics for data pipeline monitoring?
Start with freshness (time since last successful run), volume (rows processed compared to a seasonal baseline), quality (validation failures or null ratios in required fields), and runtime. These four cover most failures that downstream consumers actually notice.
How do I monitor ML model drift with Prometheus and Grafana?
Expose prediction scores or key feature values as histograms from your serving service, then compare quantiles across time windows using offset. For formal statistical drift tests, compute them in a scheduled job and push the results as gauges.
How do I keep Grafana dashboards consistent across environments?
Use Grafana's file-based provisioning for data sources and dashboards, store the JSON and YAML in version control, and deploy them through the same pipeline as your application code. Template variables let one dashboard serve many pipelines.